Reinforcement Learning
In-Hand Manipulation RL Task
Reinforcement learning-based in-hand cube reorientation task for the 16 DOF Wato hand in Isaac Lab. The policy learns to reorient a DexCube held in the palm toward commanded goal orientations using PPO (Proximal Policy Optimization).
Task Setup
| Parameter | Value |
|---|---|
| Robot | 16 DOF Wato hand (palm-up orientation) |
| Object | Isaac Nucleus DexCube, scale (0.8, 0.8, 0.8) |
| Goal command | Reorientation command, resampled on success |
| Success threshold | Orientation error < 0.4 rad |
| Episode length | 20 seconds |
| Number of environments | 2048 (default) |
| Simulation frequency | 120 Hz |
| Action decimation | 4 |
Reward Structure
The reward function combines task objectives with regularization penalties:
| Category | Term | Weight | Description |
|---|---|---|---|
| Task Rewards | Position tracking | -3.0 | L2 distance to goal position (hold in palm) |
| Orientation tracking | 10.0 | Dense rotation signal: | |
| Success bonus | 50.0 | Binary reward when error < 0.4 rad | |
| Object held bonus | 0.5 | +1/step when cube within 0.10 m of goal | |
| Angular velocity toward goal | 0.2 | Reward cube spin aligned with goal | |
| Spread activity | 0.03 | Encourages finger abduction (Wato hand) | |
| Penalties | Object away penalty | -5.0 | Terminal penalty when out of reach |
| Action rate L2 | -0.05 | Penalize jerky commands | |
| Joint velocity L2 | Penalize high joint speeds | ||
| Action L2 | Penalize large action magnitudes |
Termination Conditions
| Condition | Threshold |
|---|---|
| Time out | Episode length > 20 seconds |
| Max consecutive success | 50 successful reorientations in one episode |
| Object out of reach | Cube drifts > 0.3 m from robot root |
| Orientation stagnation | Error stays > 0.5 rad for 150 consecutive steps |
Training Details
- Algorithm: PPO with GAE (Generalized Advantage Estimation)
- Gamma: 0.998
- Entropy coefficient: 0.0001
- Steps per environment: 48
- Action smoothing: EMA joint-position targets, alpha = 0.85
- Max iterations: 5000
The task is implemented in Isaac Lab and adapted from their in-hand manipulation examples. Checkpoints are saved to logs/rsl_rl/wato_hand_cube/.
Additional RL Demonstrations
Manipulation Task Setup
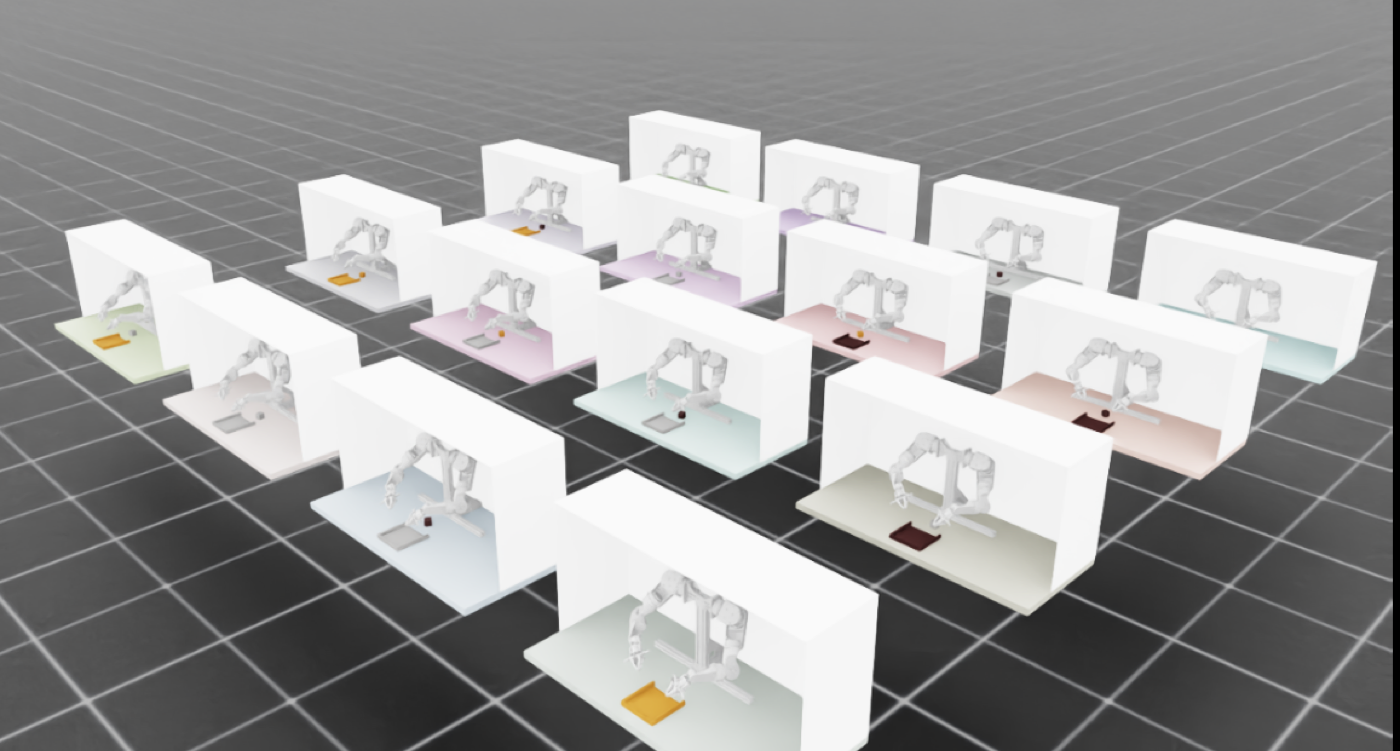
Parallelized manipulation task environments for RL training.